Text-Generation-WebUI Client
This requires you to have a Text-Generation-WebUI instance running
If you do not have a Text-Generation-WebUI instance running, you can follow their setup instructions in their GitHub repository.
If you want to add a Text-Generation-WebUI client, go to Settings → Connections → Clients, click Add client and pick Text-Generation-WebUI (ooba) from the client type menu.
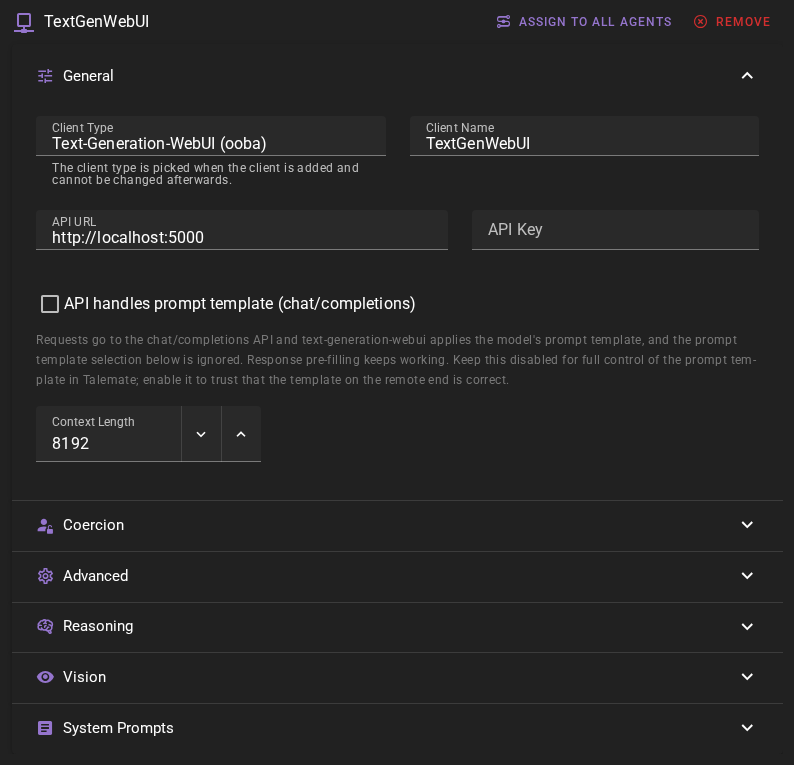
Should work out of the box with a local Text-Generation-WebUI instance
The default values should work with a local Text-Generation-WebUI instance if you have followed their setup instructions and are running the server on the default port.
Click Save in the toolbar to add the client.
Ready to use
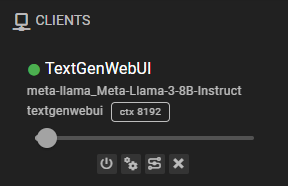
Once it is added, the client should appear in the clients list and should display the currently loaded model.
Settings
Client Name
A unique name for the client that makes sense to you.
API Url
The URL of your Text-Generation-WebUI instance, without any path. For example, http://localhost:5000.
API Key
If the Text-Generation-WebUI instance requires an API key, you can set it here.
API handles prompt template (chat/completions)
This will cause requests to go to the chat/completions API instead and Text-Generation-WebUI will be in control of the prompt template. Coercion (pre-filling the beginning of the response) keeps working through the API's continue_ mechanism.
This is off by default. It is a trade-off: keep it disabled for full control of the prompt template in Talemate, or enable it to trust that the template configured on the remote end is correct — useful when you don't know which prompt template to pick. While it is enabled, Talemate's own prompt template selection for the client has no effect.
With reasoning models, Text-Generation-WebUI separates the thinking from the response on its end, so no reasoning pattern is needed in this mode — the reasoning is captured automatically. Talemate also tells the model's template whether to think, following the client's Reasoning setting, so models with switchable thinking (such as Qwen3 and Qwen3.5) answer directly while reasoning is off.
Context Length
The number of tokens to use as context when generating text. Defaults to 16384.
Common issues
Generations are weird / bad
Make sure the correct prompt template is assigned.
No model loaded
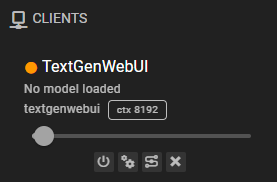
If your client displays a No model loaded message, it means that you haven't loaded a model yet. Go to your Text-Generation-WebUI instance and load a model.
Could not connect
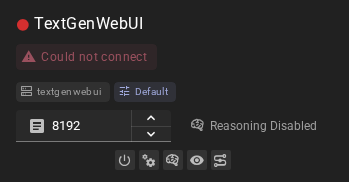
This means that either your Text-Generation-WebUI instance is not running, the url is incorrect, or the connection is somehow blocked. (For example, by a firewall)
Response Length Enforcement
Controls whether token limits and/or human-readable response length instructions are sent with prompts. Defaults to Limit tokens and send instructions.
See Response Length Enforcement for details.